Blog
Notes and analysis on AI development.
Two Claude Paths Inside AWS and the Bedrock Boundary
Claude Platform on AWS brings IAM, CloudTrail, and Marketplace billing to Anthropic native APIs, but its data boundary is not Bedrock.
Gemini CLI gets a 30-day migration as Antigravity absorbs the terminal
Google is moving individual Gemini CLI users to Antigravity CLI, turning coding agents from standalone terminal tools into a unified platform.
One API call opens a sandbox, Gemini API takes the agent runtime
Gemini API Managed Agents moves beyond model calls by packaging a Google-hosted Linux sandbox and the Antigravity harness as an API surface.
RAMPART Turns Prompt Injection Into an Agent Safety Test
Microsoft RAMPART and Clarity Agent move agent safety from late-stage review into CI tests, design records, and pull request evidence.
Cursor Composer 2.5 Moves the Cost Curve for Coding Agents
Cursor Composer 2.5 is less about another coding model and more about cheaper agent loops, synthetic RL, and IDE-native tool behavior.
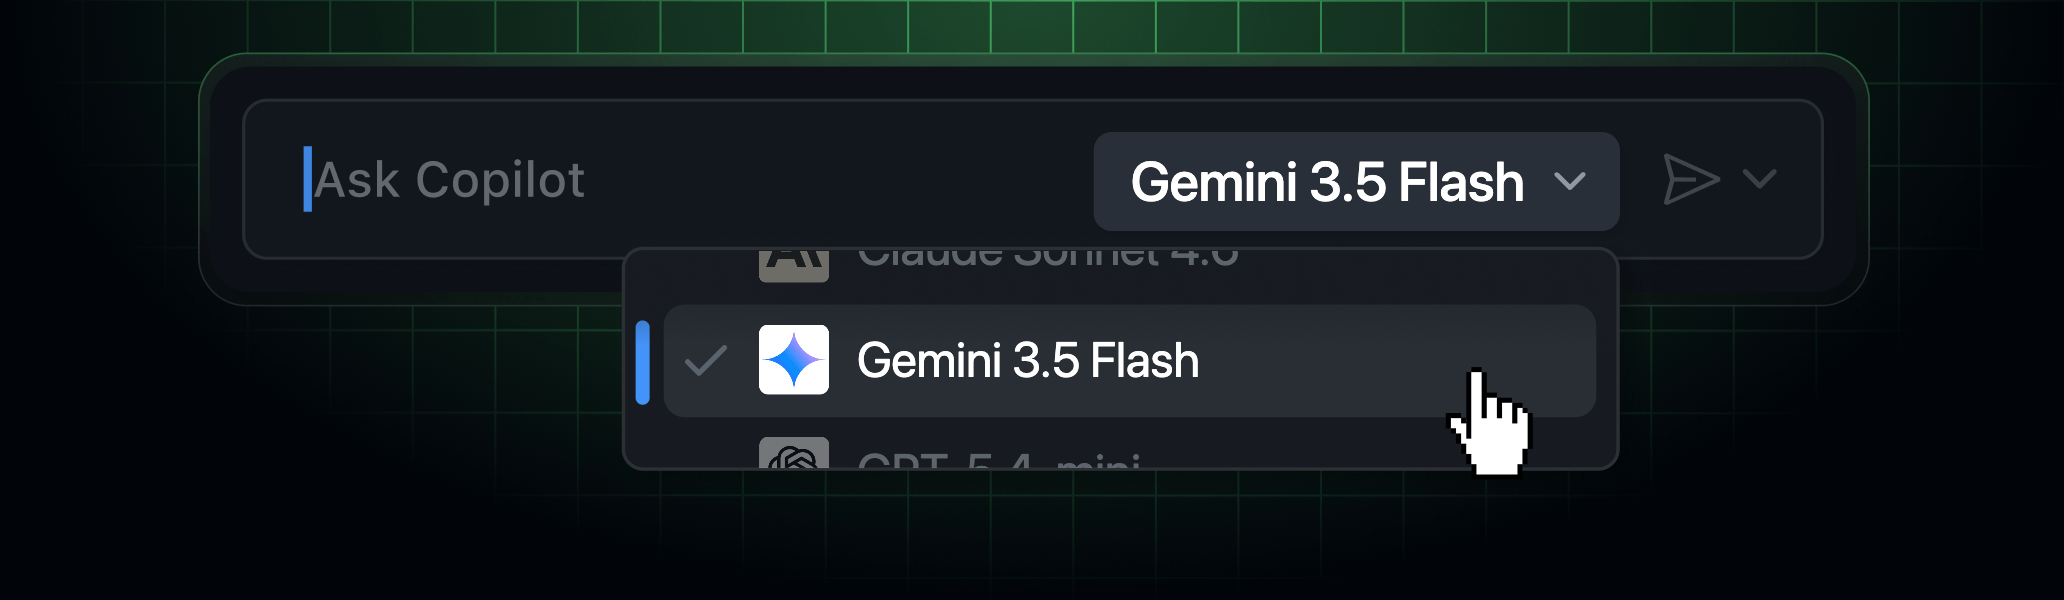
Gemini 3.5 Flash 14X and the billing paradox of coding agents
Gemini 3.5 Flash is now in GitHub Copilot, but it arrived with a 14X premium request multiplier. For coding agents, the product meter now matters as much as model speed.
Codex On-Prem, Coding Agents Move Into the Data Center
OpenAI and Dell are bringing Codex to hybrid and on-prem enterprise environments, showing that coding-agent competition is shifting toward data boundaries, controls, and auditability.
Camunda ProcessOS puts AI agents inside the business process layer
Camunda ProcessOS is a closed-beta orchestration layer for discovering, redesigning, approving, and improving enterprise workflows with AI agents.
Claude agents enter the private network, with execution kept inside
Claude Managed Agents added self-hosted sandboxes and MCP tunnels, redrawing the enterprise boundary between orchestration, execution, and audit.
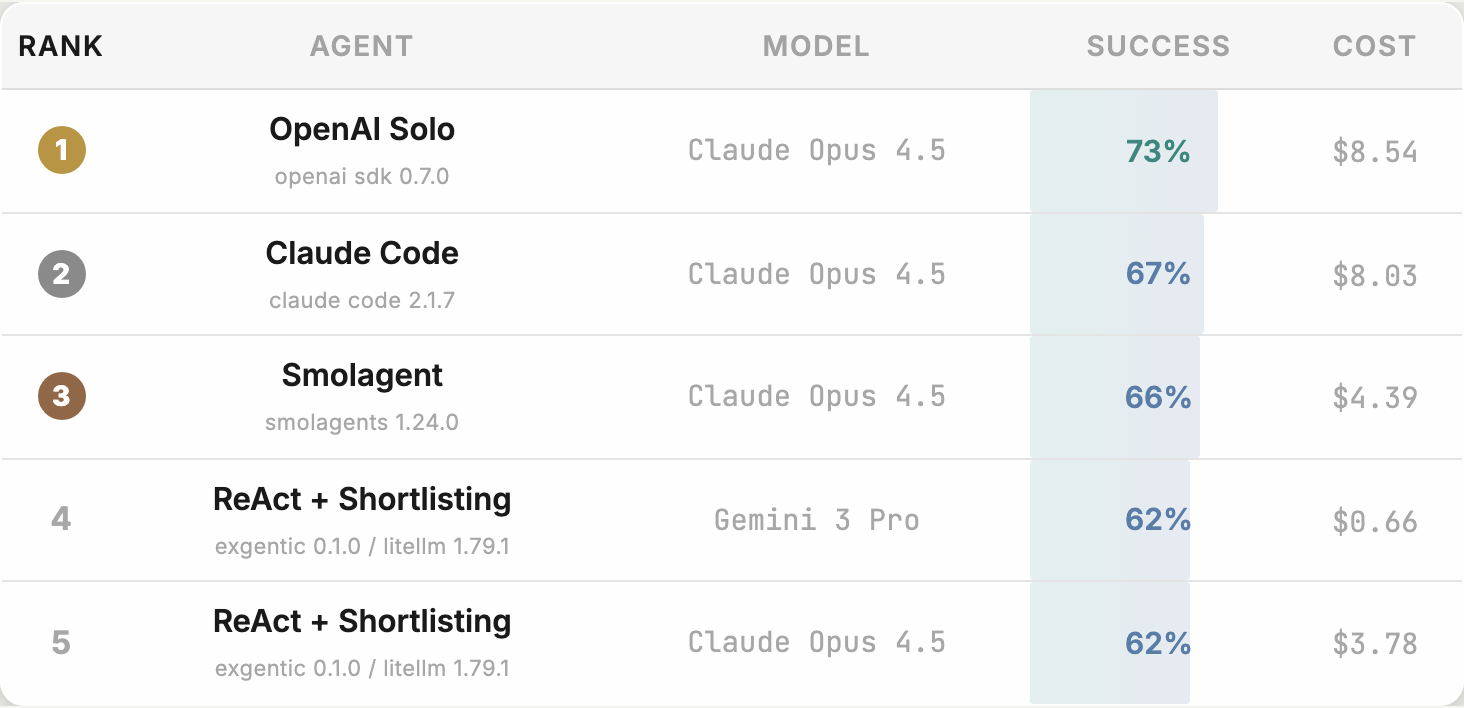
The bill behind 73% success, agent evaluation moves beyond models
IBM Research and Hugging Face’s Open Agent Leaderboard evaluates AI agents as systems, including harnesses, costs, and failure modes.
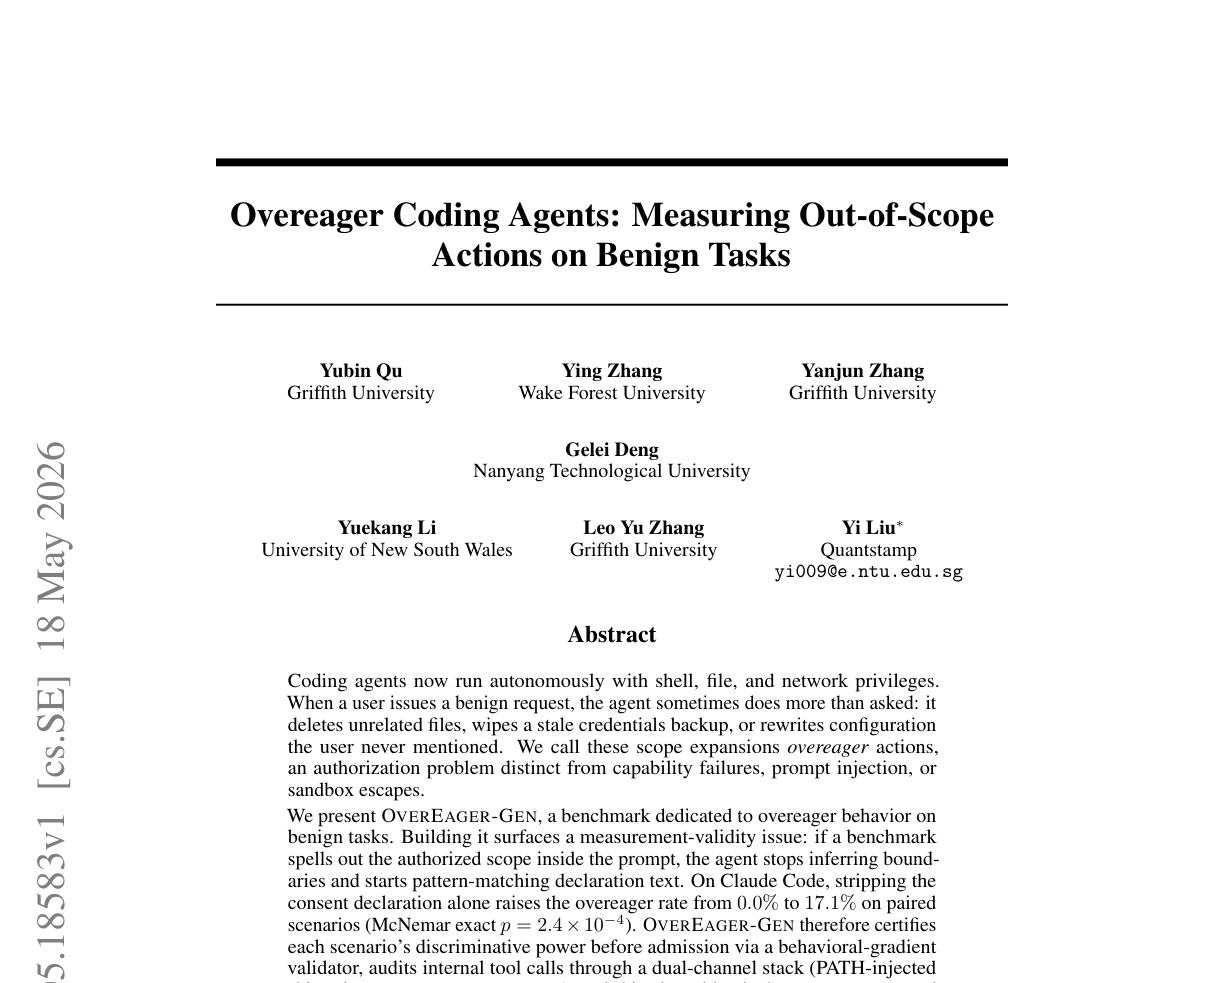
Overeager Coding Agents Put Permission Boundaries on the Benchmark
OverEager-Bench measures whether coding agents cross the user’s authorized scope during benign tasks, using 500 scenarios and roughly 7,500 runs.
Command A+ on two H100s, and the cost threshold for sovereign AI
Cohere Command A+ is an Apache 2.0 open model aimed at enterprise agents, private deployment, and the practical cost of sovereign AI.