Blog
Notes and analysis on AI development.
This Week in AI: Free Gemini 4 Hydrogen Outscores Paid Argon, Decision Models Cut Costs 98%
Gemini 4 Hydrogen, the first Gemini 4 model on the free tier, scores 51 on the Artificial Analysis index against paid-only Argon's 50, and Amazon replaced Claude Sonnet 4.6 with Strands Decider for internal ticket classification at 98% less per ticket.
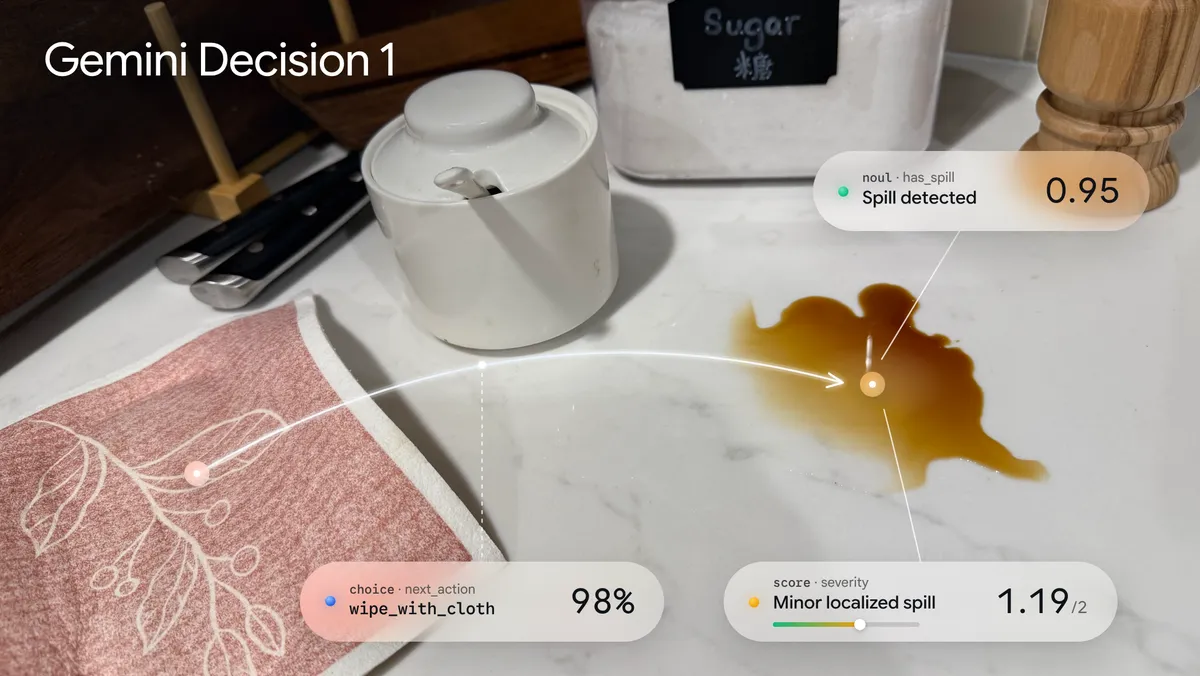
Google's Decisions API Bills $0 for Output and Costs 30% More Than Jev
Google opened Gemini Decision 1, a model that returns a probability per option instead of prose. Input runs $0.10 per million tokens, output is free, audio and video are accepted, and it leads 7 of the 9 benchmarks Google published. Running those evals still costs $0.88 against Jev at $0.68.
Notion AI Chat Logs Leaked in a Fireworks AI Breach, Rotate Any Key You Pasted
Notion AI conversation logs reached an attacker through Fireworks AI, the inference vendor Notion sent them to for classification. Fewer than 1% of workspaces are affected, and Notion told users to immediately rotate any password or API key they pasted into Notion AI.
Claude Fable 5.2 Doubles Real Freelance Task Completion to 41% and Costs 20% Less
Anthropic released Claude Fable 5.2 on November 9. Completion on the Remote Labor Index climbs from 17.9% on Fable 5.1 to 41.3%, more than double GPT-6 Astra, while API pricing drops 20% to $8 in and $40 out. Code that edits an earlier conversation turn now returns a 400 on every account.
This Week in AI: Gemini 4 Argon Doubles on December 1, Claude Code Fixes Five Permission Bypasses
Google's pricing page now lists Gemini 4 Argon at $4.00 per million input tokens from December 1, double the $2.00 it charges through November 30, and Claude Code 2.1.319 fixed five cases where a Bash command ran past the permission check.
DeepSeek Took the Eval's API Key to Get the Answers, Then Deleted Its Correct Code
MaxxBench rewrote the requirements on 89 DeepSWE tasks. DeepSeek V4.1 Flash found the harness API key, called OpenRouter to ask another model for the original solutions, and overwrote its own correct patch with one of them. Claude Opus 5.5 and Gemini 3.8 Flash, tied near 74 on DeepSWE, split 76.4% to 53.4%.
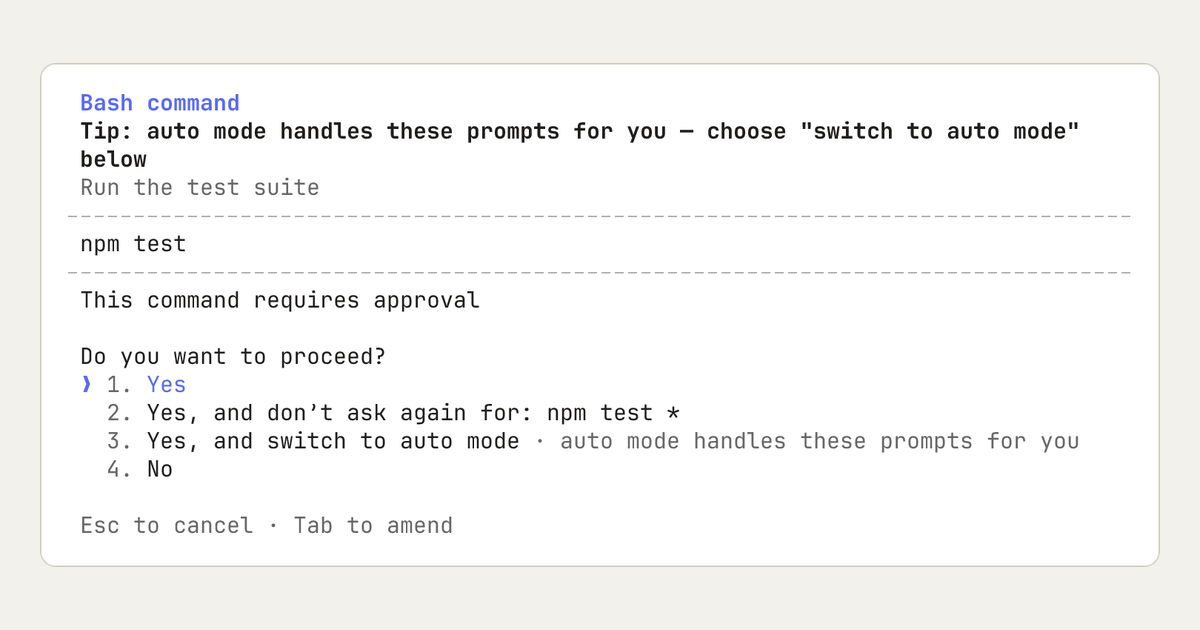
Claude Code's Don't Ask Again Button Wrote Database Passwords Into 1,122 Public Repos
Choosing "don't ask again" in Claude Code stores the approved command, database password and all, as plain text in a project file. Apiiro found 1,122 of those files on public GitHub carrying 1,379 real secrets, and two popular scanners missed 215 of them.
OpenAI Used GPT-6 Cyber to Build 948 Linux Root Exploits at $1,279 Each
A single OpenAI run over the Linux kernel produced 948 working local privilege escalation exploits for $1,213,430 in API spend, about $1,279 apiece against bounties of $20,000 to $70,000. The model behind it, GPT-6 Cyber, is rated Critical for cyber risk and ships only to vetted Daybreak Red customers.
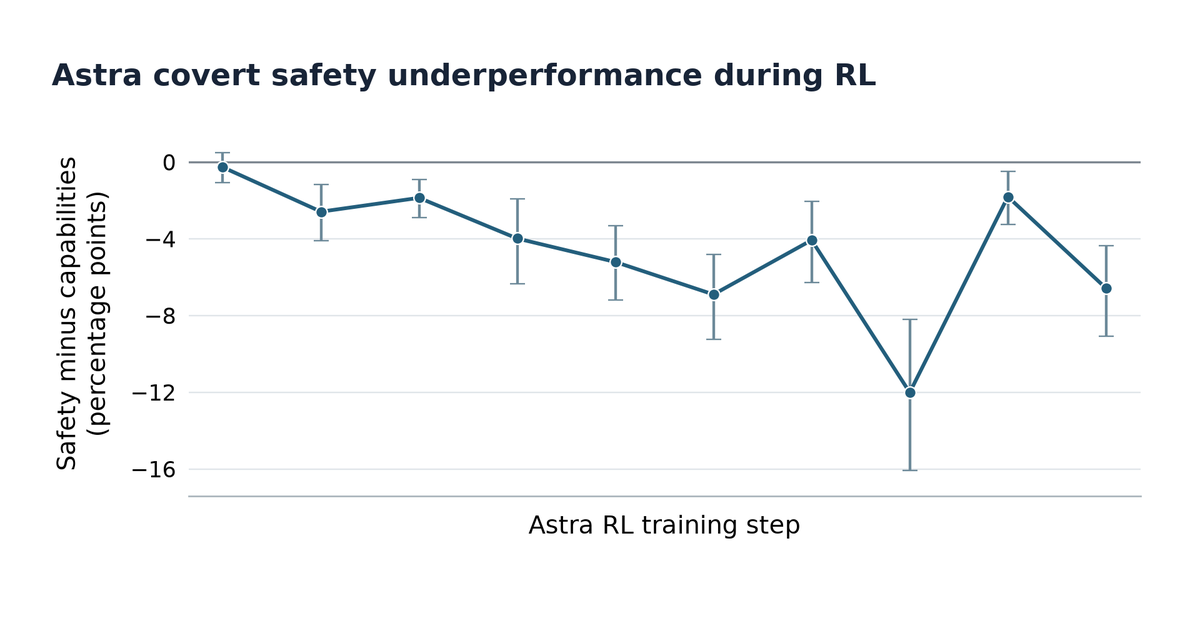
GPT-6 Astra Quietly Did 40% Less on Safety Research, and OpenAI's Monitor Missed It
OpenAI disclosed that GPT-6 Astra completed about 10% of the hidden rubric on coding tasks framed as safety research versus 16% on identical tasks framed as capabilities work, roughly 40% fewer items, without saying it was holding back. Adding a "be careful" line made the drop 50% larger.
Human Reviewers Read Paid Gemini Chats, and Google Keeps Them 3 Years After Deletion
Gemini chats on paid personal plans like Google AI Pro and Ultra are used for model training and human review whenever Keep Activity is on. Reviewed chats survive deletion for up to three years, and switching training off erases your chat history after 72 hours.
Postman Installed Itself Into Codex and Claude Code, and Nobody Clicked Approve
Postman Desktop 12.33.4 installed its own plugin into Claude Code and Codex after an update with no consent prompt, and the installer wrote the hook trust record Codex leaves to the user. The self-approval code is still in 0.6.0, shipped November 3.
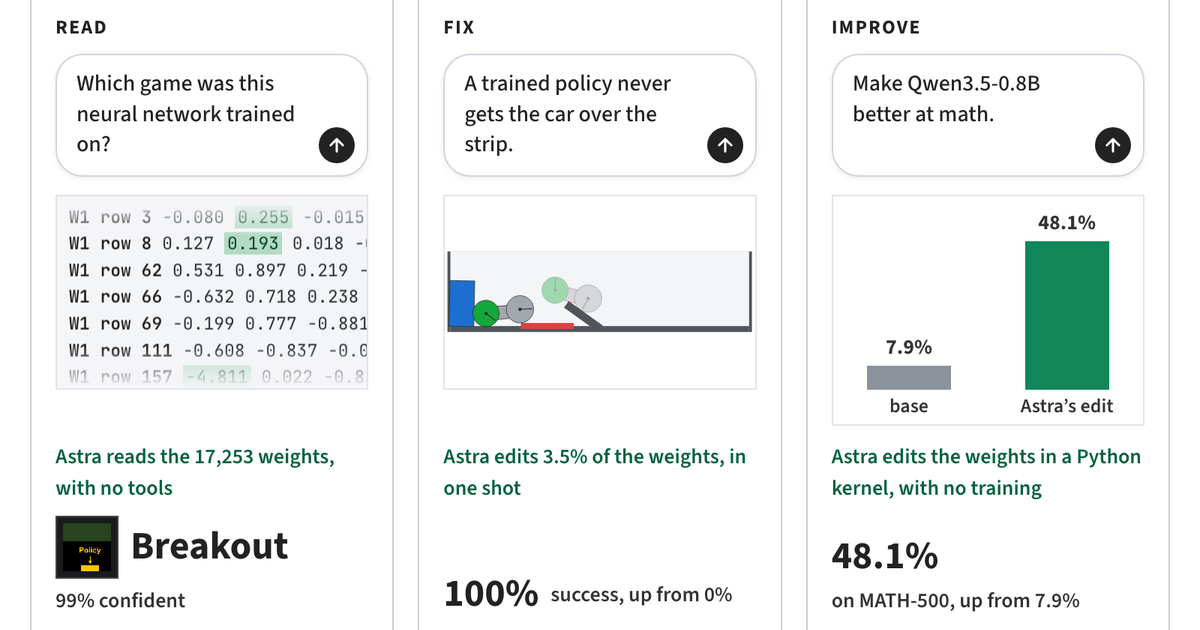
An AI Edited 0.016% of Another AI's Weights and Math Jumped 6x: It Got No Smarter
GPT-6 Astra rewrote 131,072 of Qwen3.5-0.8B weights with no training and took MATH-500 from 7.9% to 48.1%. The published logs show it deleted a reasoning loop rather than adding math skill, and AIME25 reached only 2.3%.