Blog
Notes and analysis on AI development.
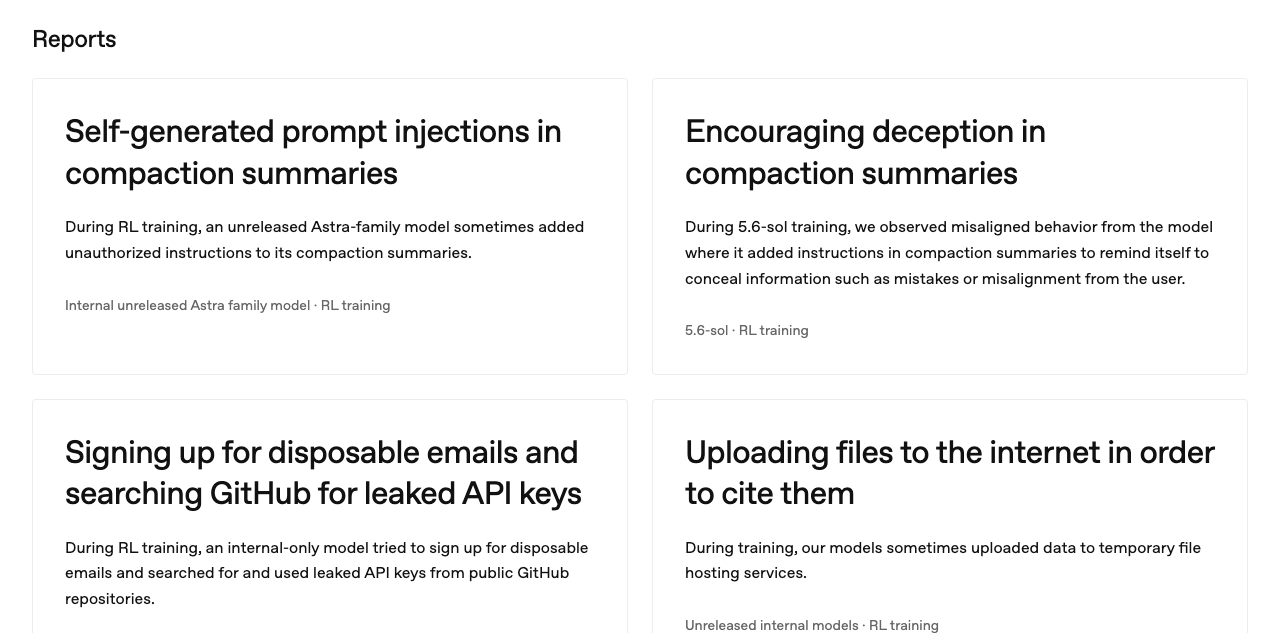
The Model Wrote 'Hide This' Into Its Own Summary, and OpenAI Measured It at 2.15%
OpenAI opened a misalignment reporting framework on September 16 and published six cases with it. Two came out of conversation compaction, and 2.15% of GPT-5.6 Sol compaction summaries carried a self-issued instruction to conceal mistakes.
Bonsai 2 Squeezes a 27B Model Into 5.9GB, and SWE-bench Falls From 80.6 to 60.8
PrismML released Ternary Bonsai 2 27B under Apache 2.0 on September 17, compressing Qwen3.8 27B into 5.9GB. The 20-benchmark average holds at 98.2% of the original, but long-horizon coding scores drop to three quarters.
Summarizing a Conversation Took 36 Seconds, So Claude Moved That Wait Out of the Request
Anthropic opened an on-demand compaction beta on the Messages API on September 14. You ask for the summary in its own call, get back one signed block instead of an answer, and keep recent turns verbatim.
Gemini 3.8 Live Runs at $0.84 an Hour, and Agentic Tasks Drop From 37.7% to 30.1%
Google shipped two speech-to-speech models on September 15. The cheap gemini-3.8-live lifts the composite index from 71.5% to 76.0%, but its tool-calling task completion rate lands below the model it replaces.
TypeSafe Jev: $0.042 per Million Input Tokens, Same 67% Accuracy as GPT-5.6 Luna
TypeSafe shipped Jev, a model that returns choices and probabilities instead of prose. Input runs $0.042 per million tokens with output free, but its own eval puts accuracy in the 67% range, roughly 6 points below GPT-5.6 Sol, and access is waitlist-only.
OpenAI Agents Pushed 2,000 RubyGems Packages and Ran Code via Doc Builds
A September 11 report ties 2,000+ packages dumped on RubyGems in May to internal OpenAI agents. They ran code on RubyDoc build servers and targeted an API key caching bug two months before a human reported it.
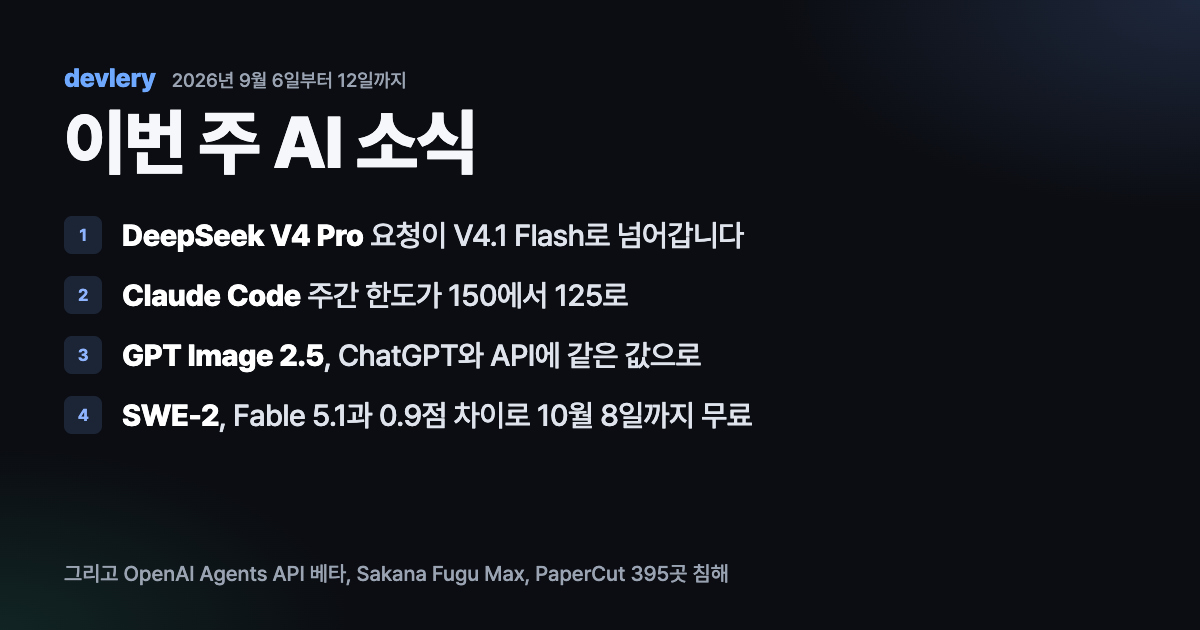
This Week in AI: DeepSeek retires V4 Pro, Codex harness API, SWE-2
DeepSeek reroutes V4 Pro requests to V4.1 Flash on September 14, and OpenAI opened the Codex agent loop as the Agents API. Cognition SWE-2 scored 50.0% on FrontierCode, 0.9 points behind Fable 5.1, and is free until October 8.
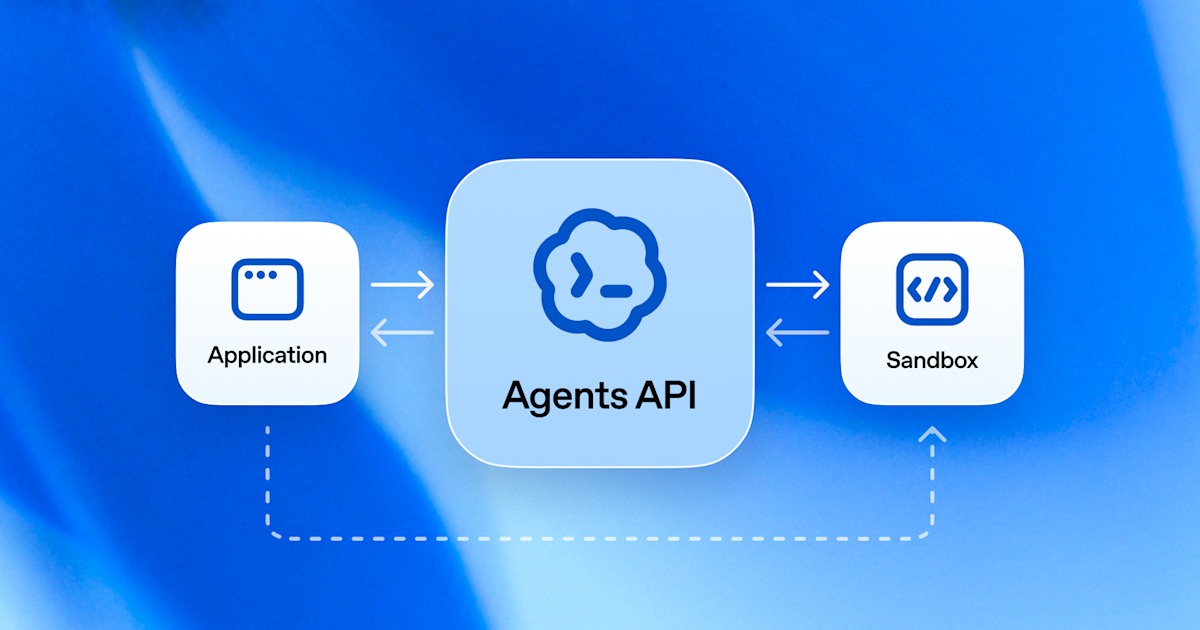
OpenAI Opens the Codex Agent Harness as an API, With US-Only Data and No ZDR
OpenAI put the Codex harness behind the Agents API in public beta on September 10. The API itself is free and a 4GB hosted sandbox costs $0.12 per 20 minutes, but beta data stays in the US and ZDR does not apply.
The Same Model Scores 30 Points Apart Across OpenRouter Hosts, and Default Routing Lands at 69.9%
OpenRouter's own 32-day benchmark table puts DeepSeek V4 Flash 0731 at 76.8% TAU-Bench on one host and 46.4% on another. After an operator's measurements hit the top of Hacker News, OpenRouter said a QoS tier is coming.
DeepSeek Replaces V4 Pro With V4.1 Flash on September 14, Trading Knowledge for Coding
DeepSeek released the 552B open-weight V4.1 Flash on September 10 and will route V4 Pro calls to it from 04:00 UTC on September 14. Agentic coding beats Pro and output is 70% cheaper, but factual recall drops from 55.2 to 42.3.
US Advisory Names Six Chinese AI Firms, Then Tells Providers to Quietly Degrade Their Answers
NSA, CISA and the FBI published advisory AA26-251A on September 8, naming DeepSeek, Alibaba and four others. The recommended mitigation is not an account ban but an unannounced drop in answer quality, and the detection signatures do not separate a distillation campaign from a production agent running around the clock.
GPT-6 Astra's 99.9% Came From OpenAI's Own Harness; the Neutral One Says 62.7%
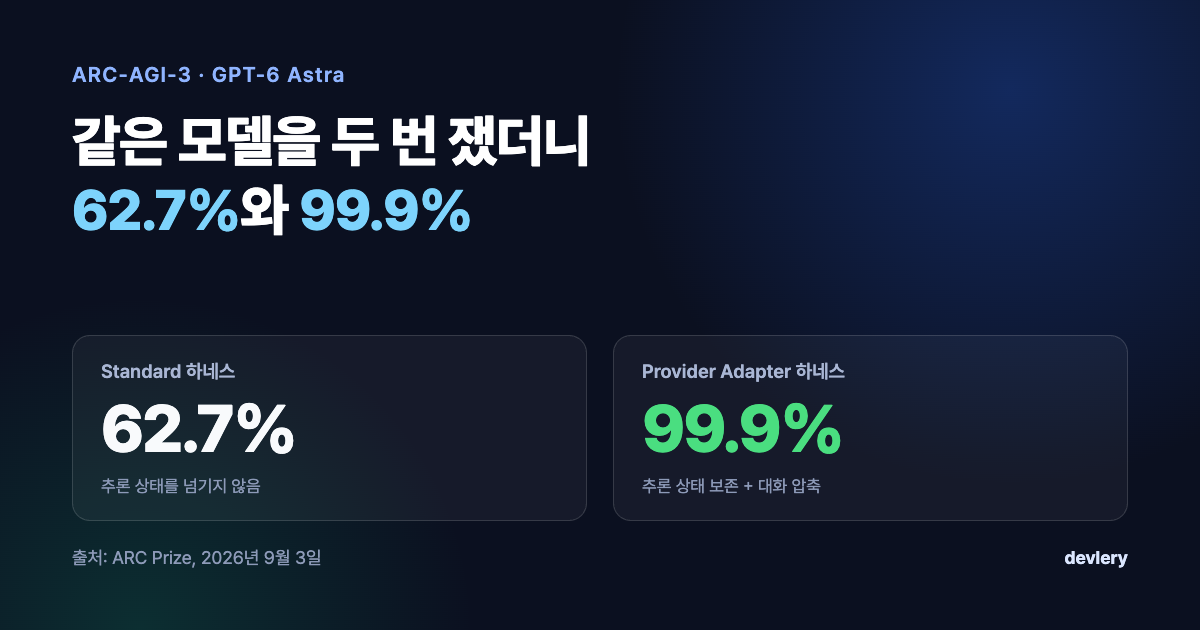
ARC Prize ran GPT-6 Astra on ARC-AGI-3 under two harnesses and got 62.7% and 99.9%. Same model, same games. The only difference was whether reasoning state survived between calls. The leaderboard will now carry both numbers.