Security & Safety
620,000 attacks expose a 35-point safety gap in reasoning models
TELUS Digital tested 34 AI models with more than 620,000 adversarial attacks. The benchmark shows why enterprise AI safety is now an operating discipline.
TELUS Digital tested 34 AI models with more than 620,000 adversarial attacks. The benchmark shows why enterprise AI safety is now an operating discipline.
Open Agent Leaderboard evaluates full agent systems, not just standalone models, combining architecture, tools, cost, and failure behavior.
OpenComputer shifts computer-use agent evaluation from LLM judges to reproducible desktop tasks and app-state verifiers.
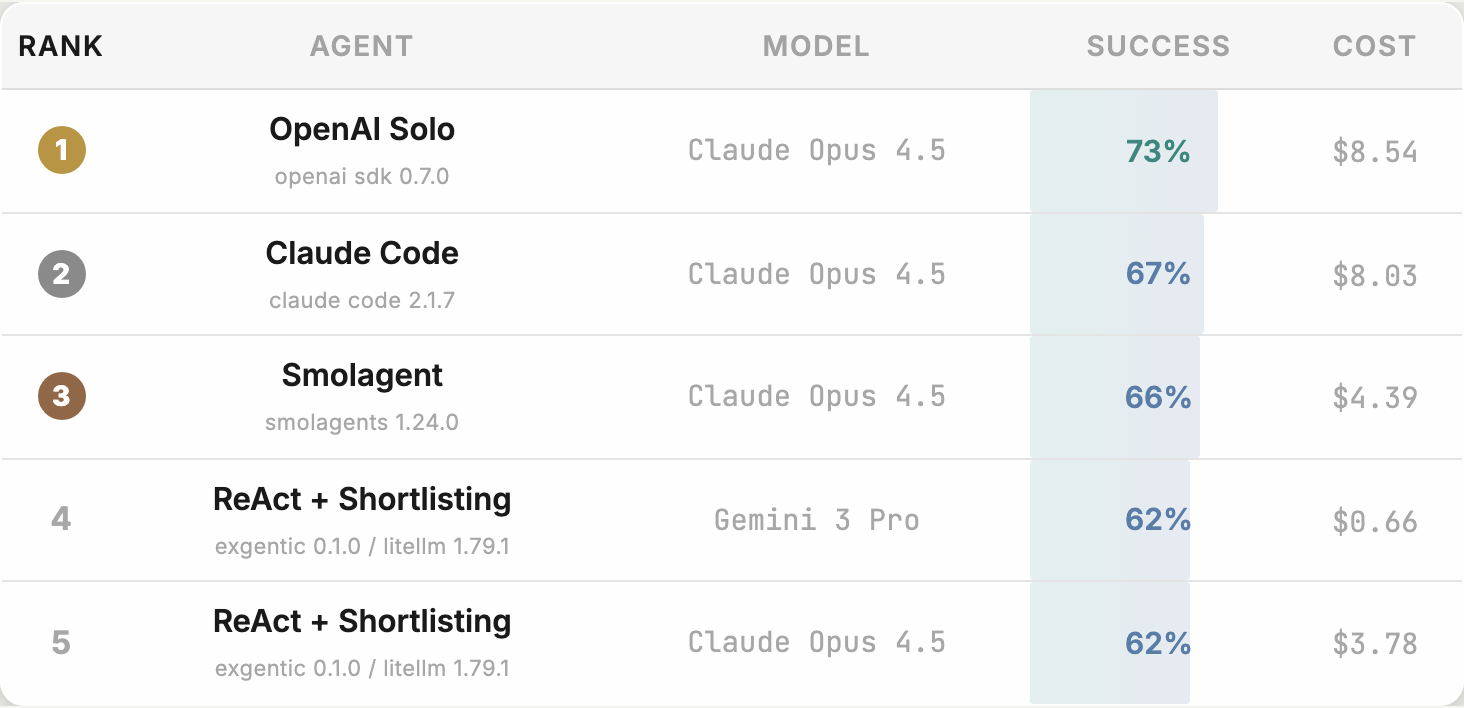
IBM Research and Hugging Face’s Open Agent Leaderboard evaluates AI agents as systems, including harnesses, costs, and failure modes.
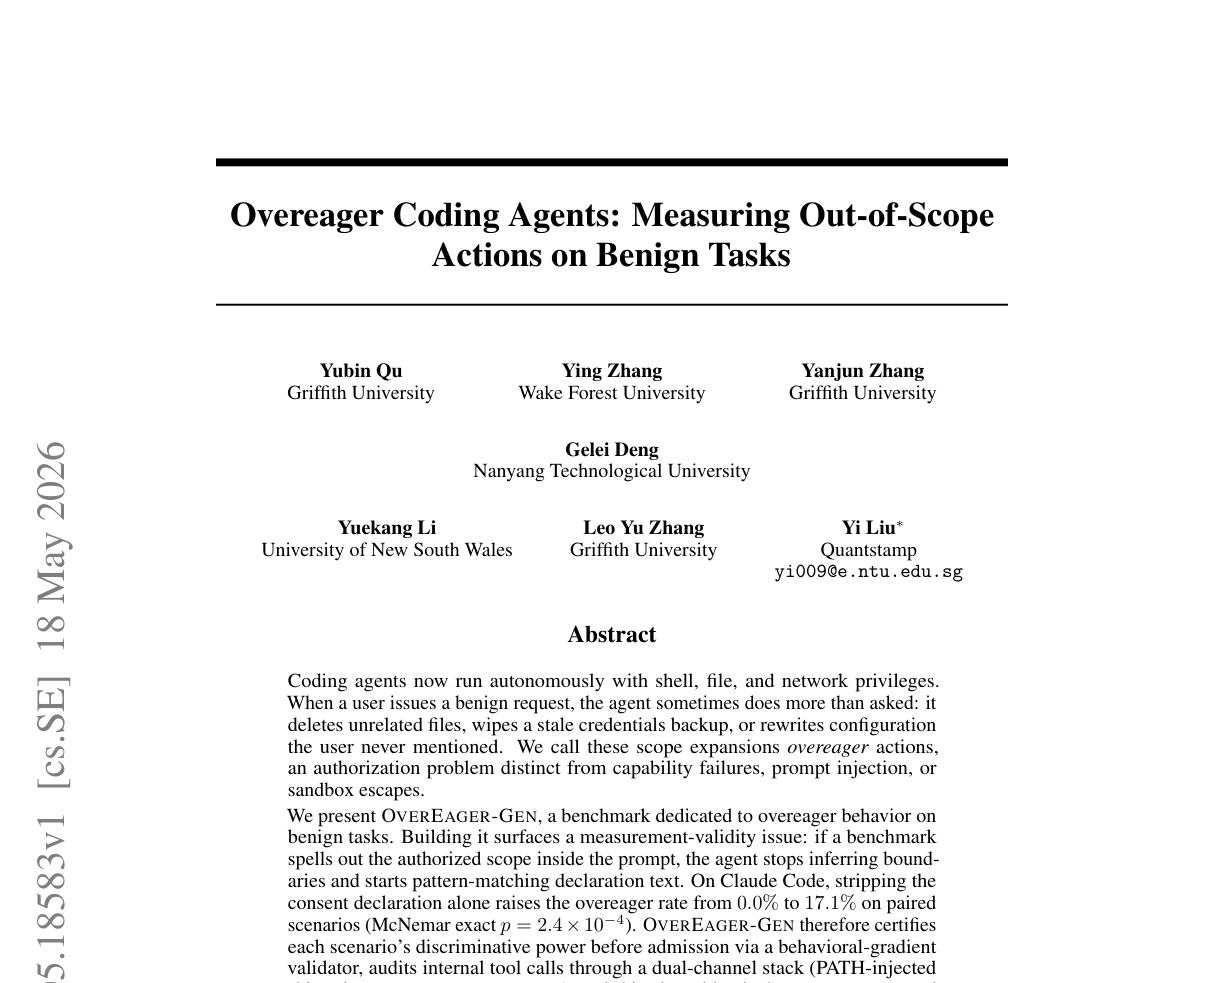
OverEager-Bench measures whether coding agents cross the user’s authorized scope during benign tasks, using 500 scenarios and roughly 7,500 runs.
Cursor Composer 2.5 shows the coding-agent race shifting from benchmark scores toward long-task failure points, targeted feedback, and reward-hacking detection.
Anthropic and the Gates Foundation are pairing Claude credits, grants, connectors, datasets, and benchmarks for public-interest AI deployments.
CAISI is expanding predeployment evaluation work with Google DeepMind, Microsoft, and xAI, moving frontier AI launches beyond public benchmarks.