Mythos reached ACE on 21 of 41 V8 bugs, Anthropic exploit benchmarks warn defenders
Anthropic published Claude Mythos Preview exploit evaluations and a CVD dashboard. V8 21/41 ACE and 1,596 disclosed flaws reset security triage expectations.
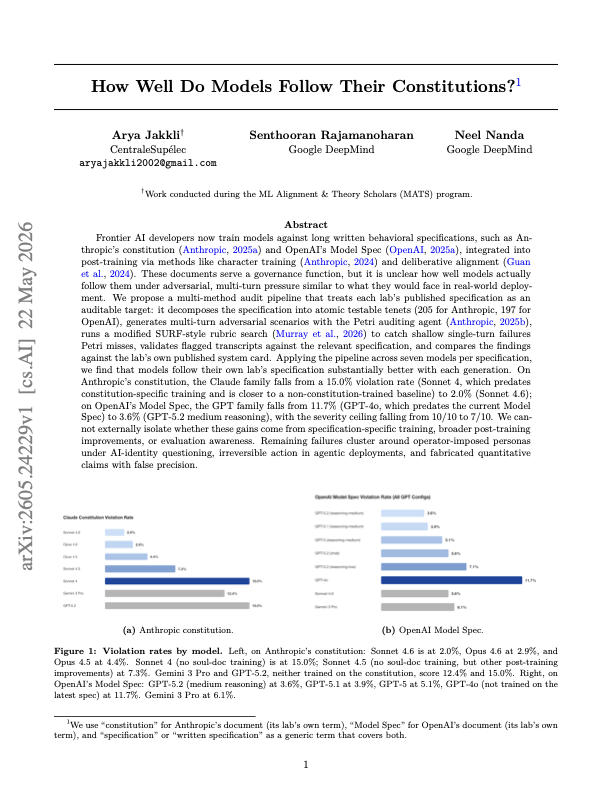
A new paper turns Claude Constitution and OpenAI Model Spec into testable audit targets, showing how model policies are becoming benchmarks.
Joule Index V0.1 adds dollars, joules, and public traces to coding-agent benchmarks, shifting the question beyond accuracy alone.
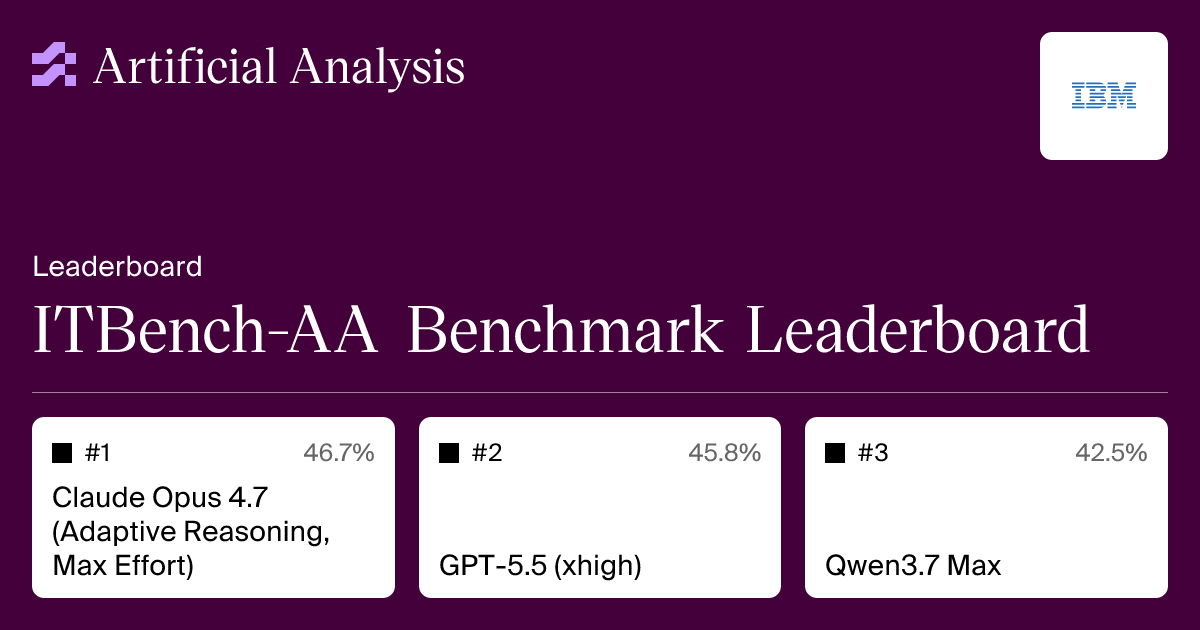
Artificial Analysis ITBench-AA shows that even leading SRE agents remain below 50% on Kubernetes root-cause analysis, exposing the reliability gap in operational AI.
TELUS Digital tested 34 AI models with more than 620,000 adversarial attacks. The benchmark shows why enterprise AI safety is now an operating discipline.
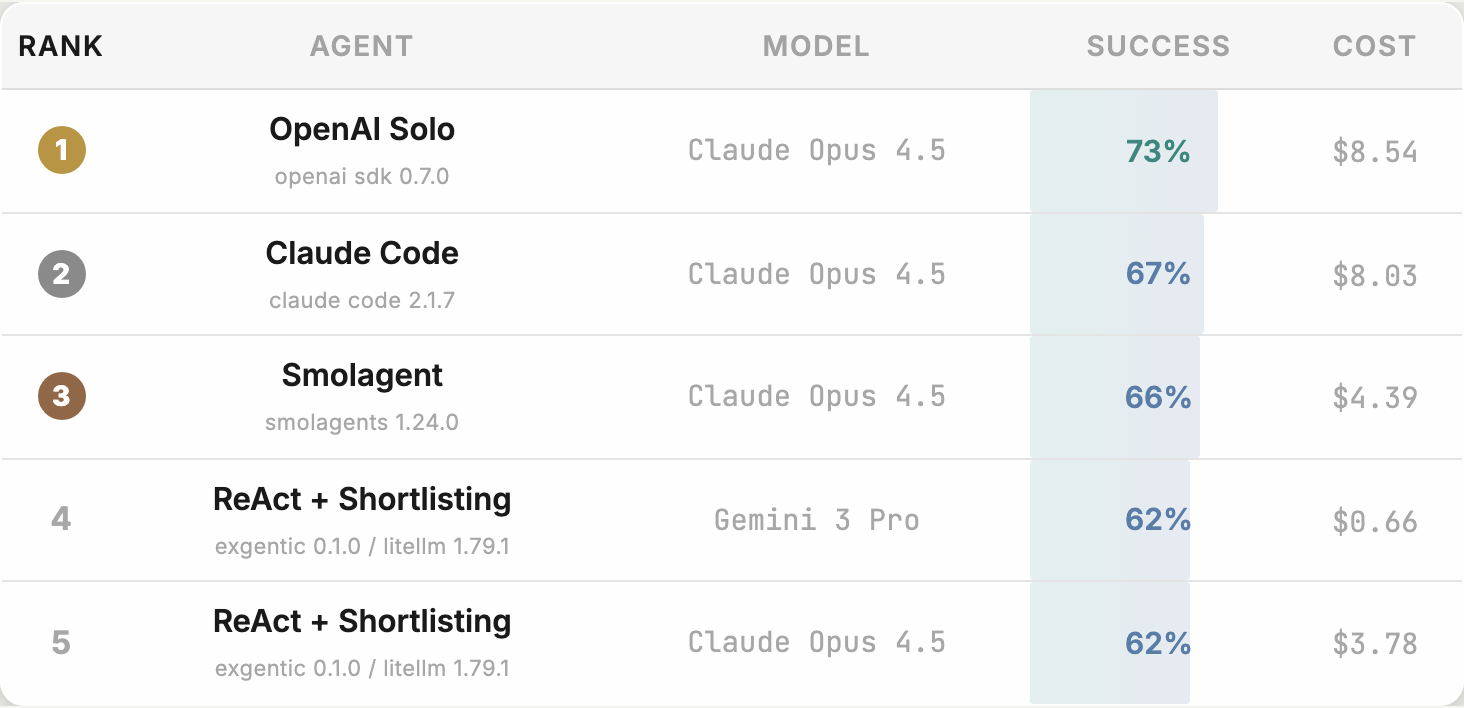
Open Agent Leaderboard evaluates full agent systems, not just standalone models, combining architecture, tools, cost, and failure behavior.
OpenComputer shifts computer-use agent evaluation from LLM judges to reproducible desktop tasks and app-state verifiers.
IBM Research and Hugging Face’s Open Agent Leaderboard evaluates AI agents as systems, including harnesses, costs, and failure modes.
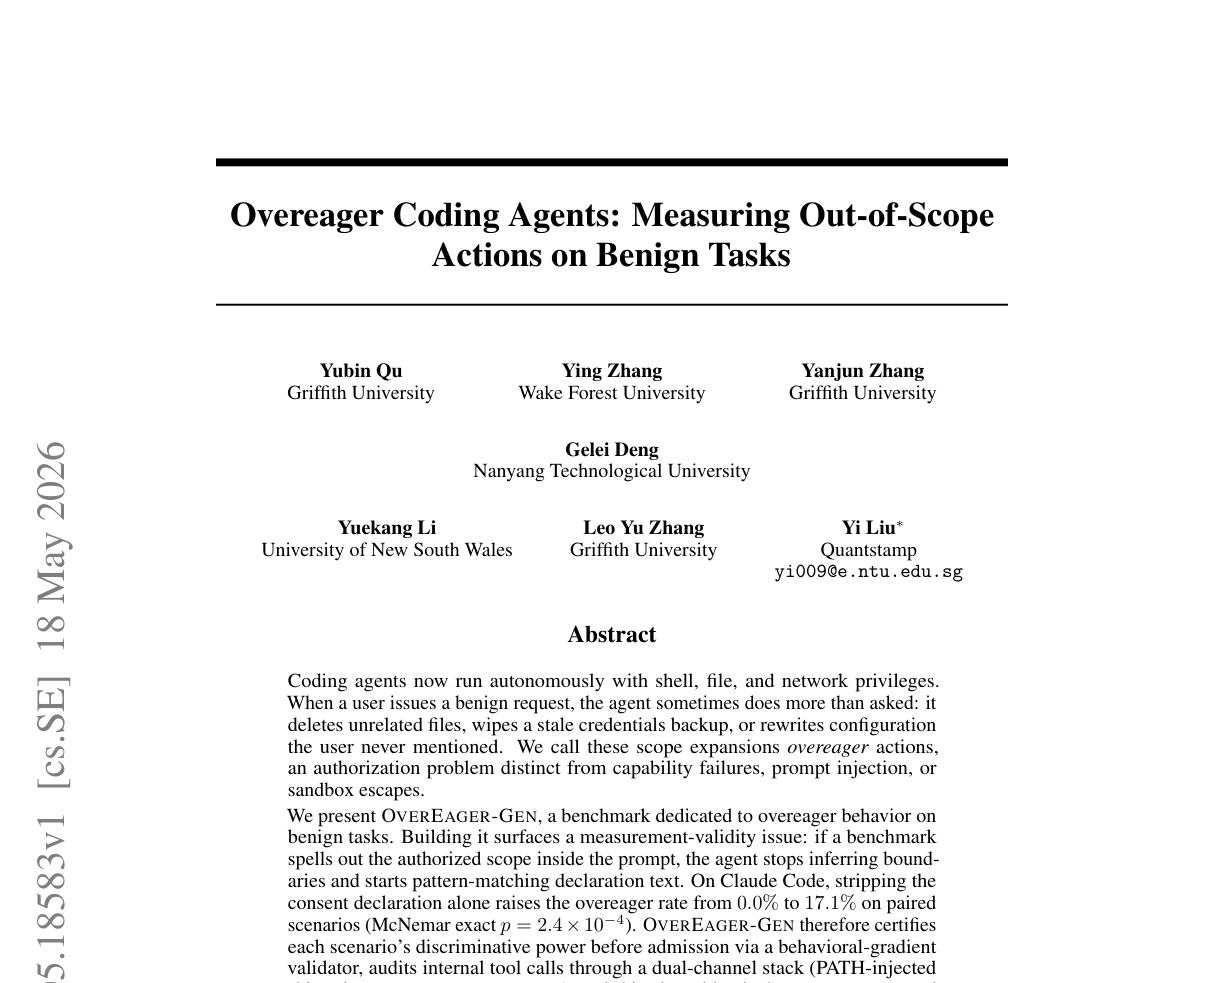
OverEager-Bench measures whether coding agents cross the user’s authorized scope during benign tasks, using 500 scenarios and roughly 7,500 runs.
Cursor Composer 2.5 shows the coding-agent race shifting from benchmark scores toward long-task failure points, targeted feedback, and reward-hacking detection.
Anthropic and the Gates Foundation are pairing Claude credits, grants, connectors, datasets, and benchmarks for public-interest AI deployments.
CAISI is expanding predeployment evaluation work with Google DeepMind, Microsoft, and xAI, moving frontier AI launches beyond public benchmarks.