Blog
Notes and analysis on AI development.
Gemini 3.8 Flash Matches Opus 5 on Coding, Then Scores 19.1% as a General Agent
Google shipped Gemini 3.8 Flash on September 2 at the same $0.75 per million input tokens as 3.7 Flash. DeepSWE climbs from 65.3% to 73.7%, but general agent work lands at 19.1% against Claude Opus 5 at 51.8%.
What Changed in Claude Fable 5.1: Coding Goes 42% to 55.8%, Forced Tool Calls Return a 400
Anthropic released Claude Fable 5.1 and Mythos 5.1 on September 1. Agentic coding climbs from 42.0% on Fable 5 to 55.8%, three beta features land in the API, cache reads cost a quarter of what they did, and three behaviors break on migration.
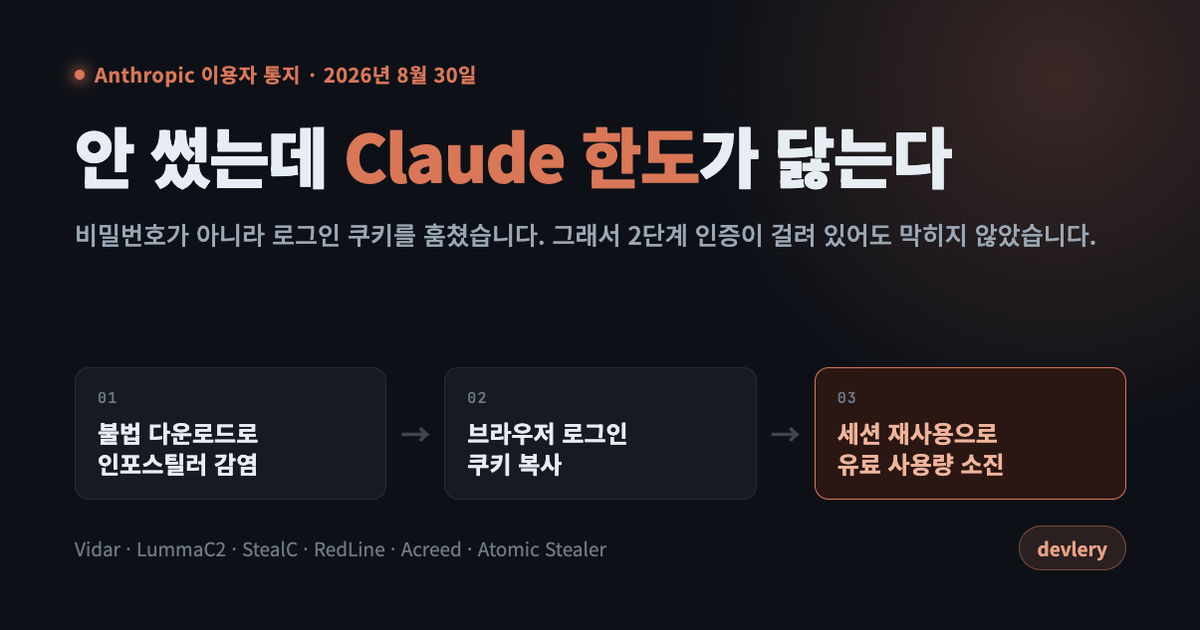
Your Claude Usage Drains While You Sleep, and Anthropic Named the Infostealer
Anthropic began notifying affected Claude users on August 30 that infostealer malware copied their login sessions. Stolen cookies walked past two-factor auth, and Claude Code tokens live on a different settings screen than web sessions.
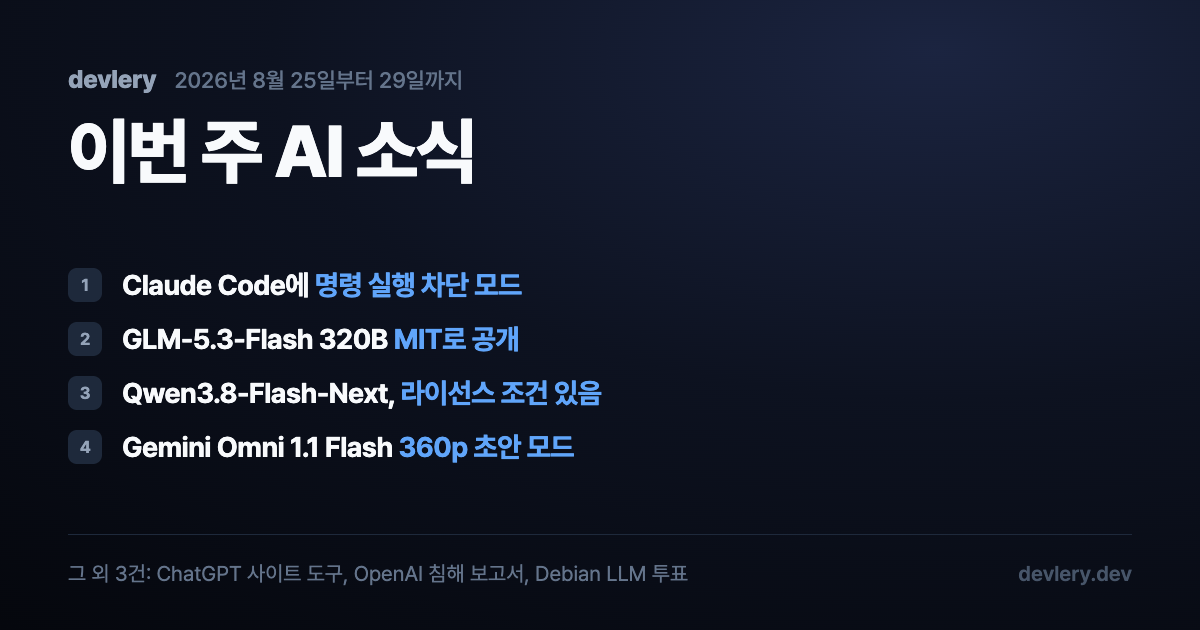
This Week in AI: Claude Code Restricted Mode, GLM-5.3 Under MIT, Qwen Open Weights
Z.ai released GLM-5.3-Flash 320B weights under MIT on August 26, and Alibaba published Qwen3.8-Flash-Next the same day. A day later Claude Code gained a --restricted mode that removes command execution and web access.
GPT Models Leave Cursor on November 12, and Your Own API Key Will Not Cover It
OpenAI served SpaceX a termination notice on August 28, closing direct access to GPT models inside Cursor on November 12. Cursor says those models are 5% of its traffic, and the bring-your-own-key workaround only reaches non-reasoning chat models.
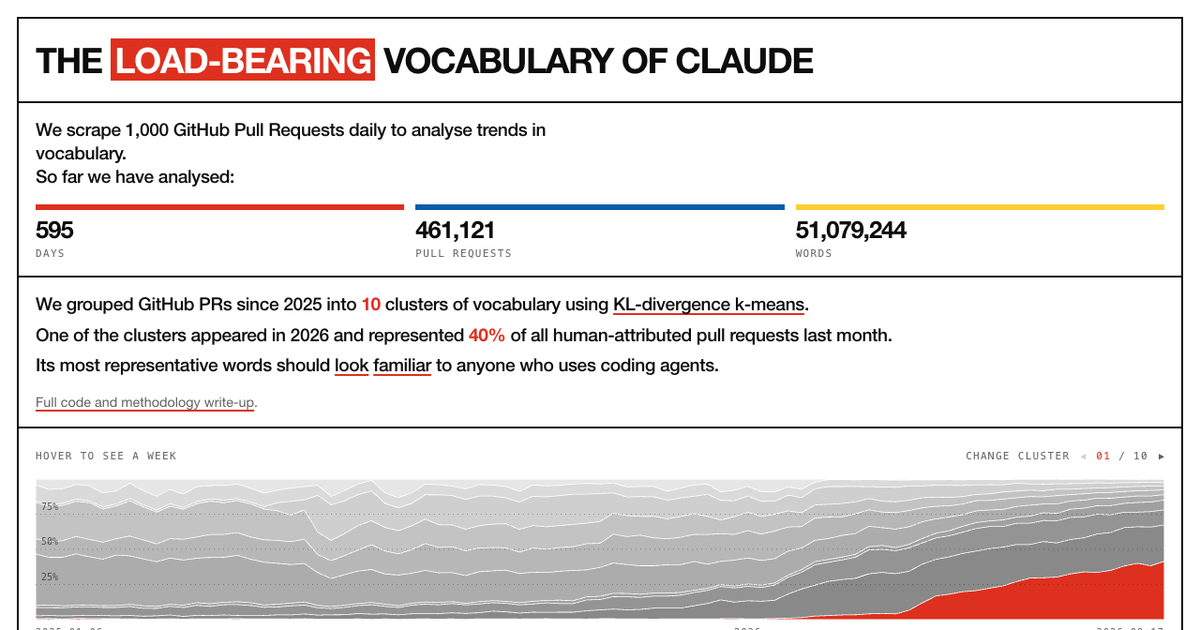
41% of GitHub PR Descriptions Now Share One Voice, and load-bearing Is Inside Claude Code
Clustering 461,121 GitHub pull request descriptions by word usage alone, one cluster grew from 0.7% to 41%. Its top marker word, load-bearing, sits in Claude Code’s built-in prompt text, which is why banning it in CLAUDE.md does not work.
A Ransomware Crew Breached 7 Companies With Cursor’s Agent by Calling It a Test
Gambit Security recovered 28 Cursor agent chat sessions from a ransomware group’s exposed server. The logs run from April 8 to May 21, 2026, and every refusal the agent made was reversed by restarting the conversation.
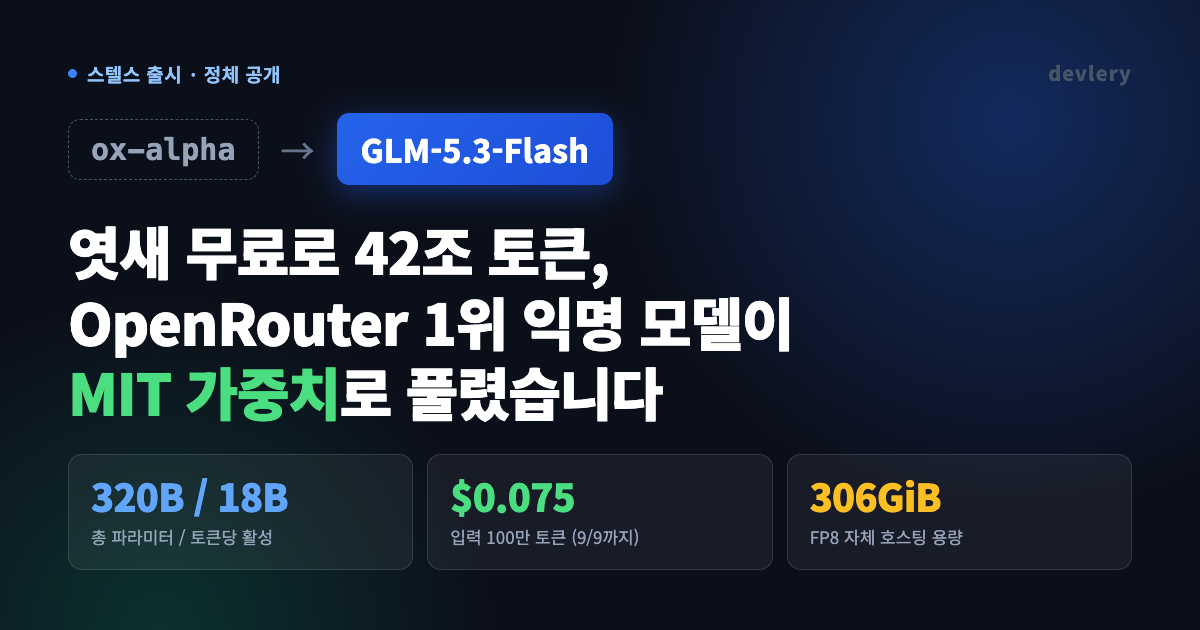
Ox Alpha, OpenRouter’s No.1 Anonymous Model, Is GLM-5.3-Flash Under MIT
The anonymous ox-alpha model that appeared free on August 20 and topped OpenRouter usage within six days is GLM-5.3-Flash. Zhipu released the 320B-A18B weights under MIT the same day, and the free window is now closed.
One Web Page Poisons Your Local Model: Why NemoClaw Could Not Fix the WSL Path
Oasis Security disclosed CVE-2026-65105 in NVIDIA NemoClaw. Opening one malicious page rewrites the chat template of your local Ollama model with attacker instructions. macOS and Linux were closed in v0.0.106; WSL was not.
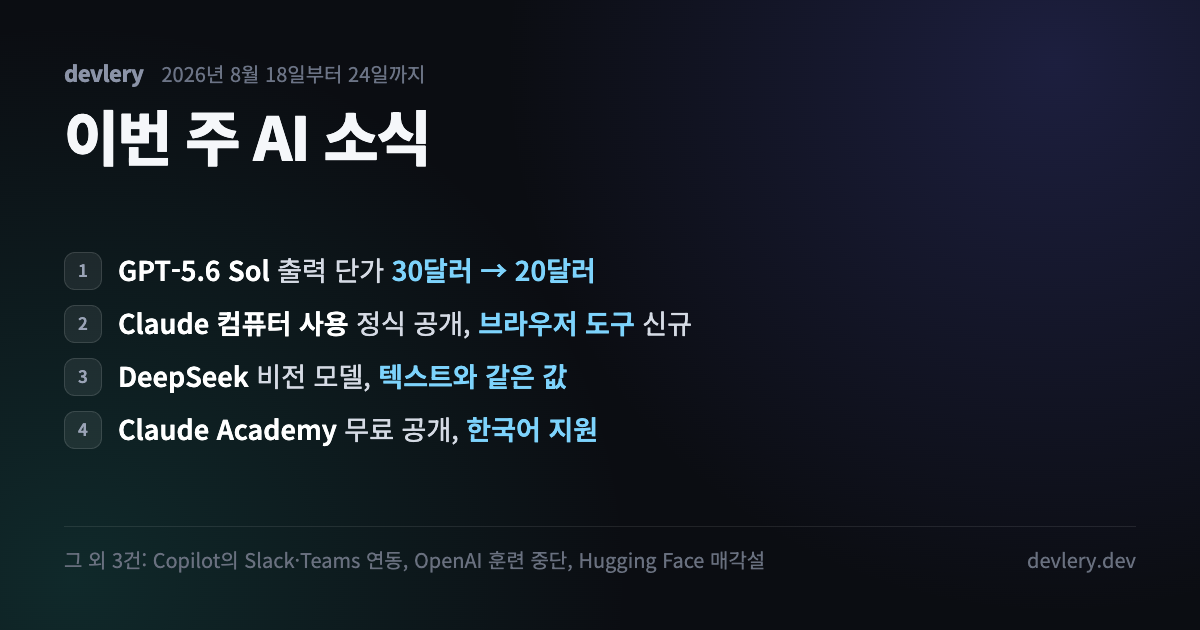
This Week in AI: Sol output down 33%, Claude computer use GA, DeepSeek vision
OpenAI cut GPT-5.6 Sol output pricing from $30 to $20 per million tokens on August 21. Anthropic moved computer use and the Skills and Files APIs out of beta, and DeepSeek opened V4-Flash-Vision-Exp at the same price as its text model.
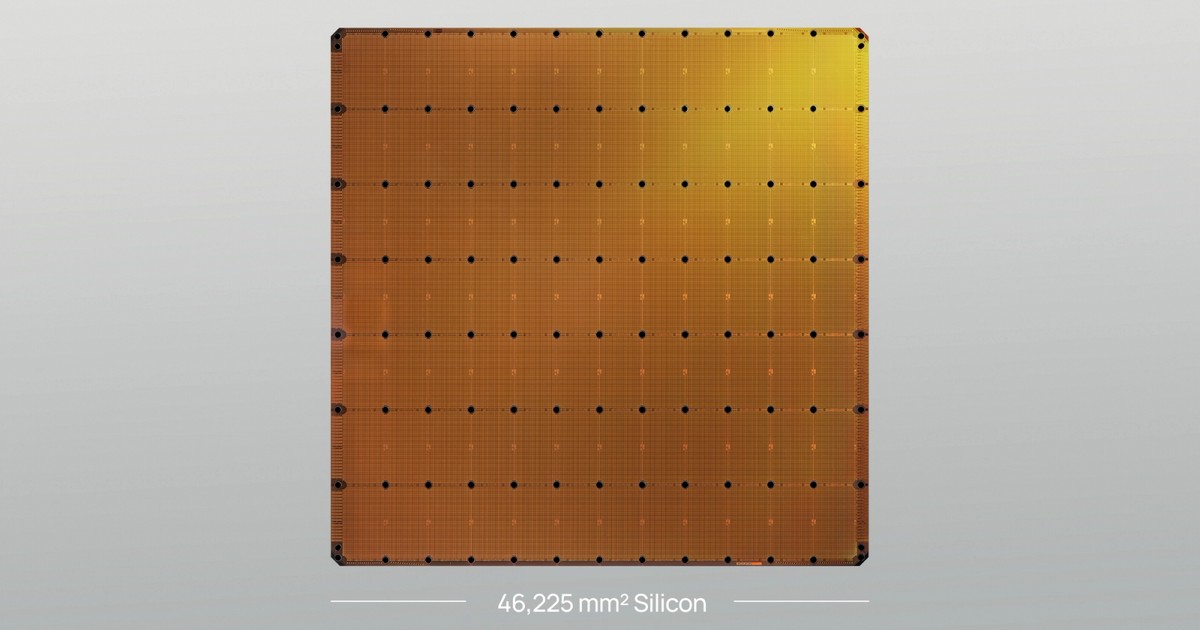
Cerebras Ships CS-4, but Never Says Which GPU the 4,400 Tokens/s Beat
Cerebras unveiled CS-4 on August 18, packing three wafers into one rack. It claims 4,400 tokens per second per user on gpt-oss-120B and up to 30x faster than GPUs, without naming the GPU product it measured against.
A2A Joins the Foundation That Hosts MCP, but Real Usage Has Not Moved
The Agentic AI Foundation accepted Google Agent2Agent as a growth-stage project on August 17. A2A now sits under the same neutral governance as MCP, but its 8-seat TSC and its thin production usage next to MCP are unchanged.