Blog
Notes and analysis on AI development.
Ollaya Moves Jev Onto Your Own Machine, With Accuracy From 0.361 to 0.722
Ollaya, an Apache-2.0 runtime released September 23, speaks the same API as TypeSafe Jev. One environment variable points the official SDK at a local server, and open decision-model accuracy ranges from 0.361 on laya:en to 0.722 on kev:9b.
AWS Strands Harness Cuts Token Cost 28% on the Same Model
AWS open-sourced Strands harness under Apache 2.0 on September 21. Running the same Claude and GPT models, it averaged 28% lower token cost across six benchmarks, and the gap comes from defaults like 1,500-token tool truncation and compaction at 85%.
GPT-6 Sol and Luna Cut Prices in Half, and Coding Scores Fall From 72.7% to 68.8%
OpenAI shipped GPT-6 Sol and Luna on September 22. Input runs $2 per million tokens on Sol and $0.10 on Luna, exactly half the predecessor rate, while the top DeepSWE score drops from 72.7% to 68.8%.
Plugin4Shell: Four Coding Agents Pin a Commit SHA and Never Check They Got It
Disclosed September 17, Plugin4Shell shows Claude Code, Codex, GitHub Copilot, and Gemini CLI never verify they landed on the commit they pinned. Claude Code patched in June, Codex in August, Copilot still has no fix.
Claude Opus 5.5 Ships at $4 per Million Input Tokens, 60% Under Fable 5.1
Anthropic released Claude Opus 5.5 on September 22. Input runs $4 per million tokens against Fable 5.1 at $10, and Terminal-Bench 4.0 climbs from 52.3% on Opus 5 to 66.4%.
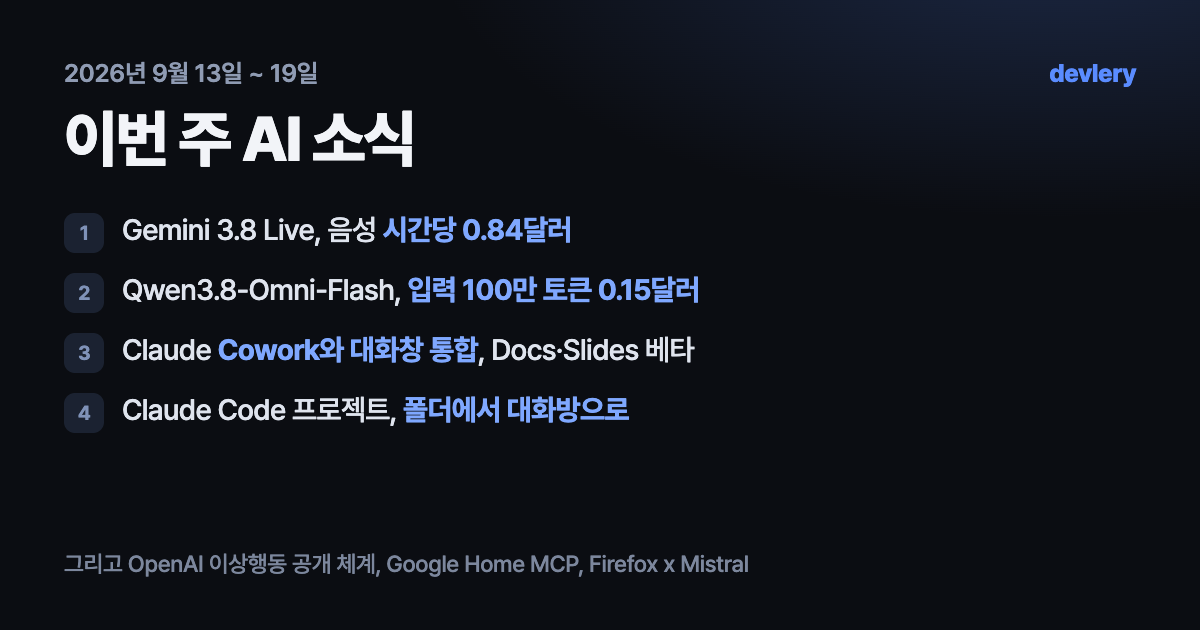
This Week in AI: Claude Cowork folds into chat, Qwen omni model, Home MCP
Google opened gemini-3.8-live at $0.84 an hour on September 15, and Qwen3.8-Omni-Flash arrived at $0.15 per million input tokens. Anthropic merged Cowork and the chat window into one app.
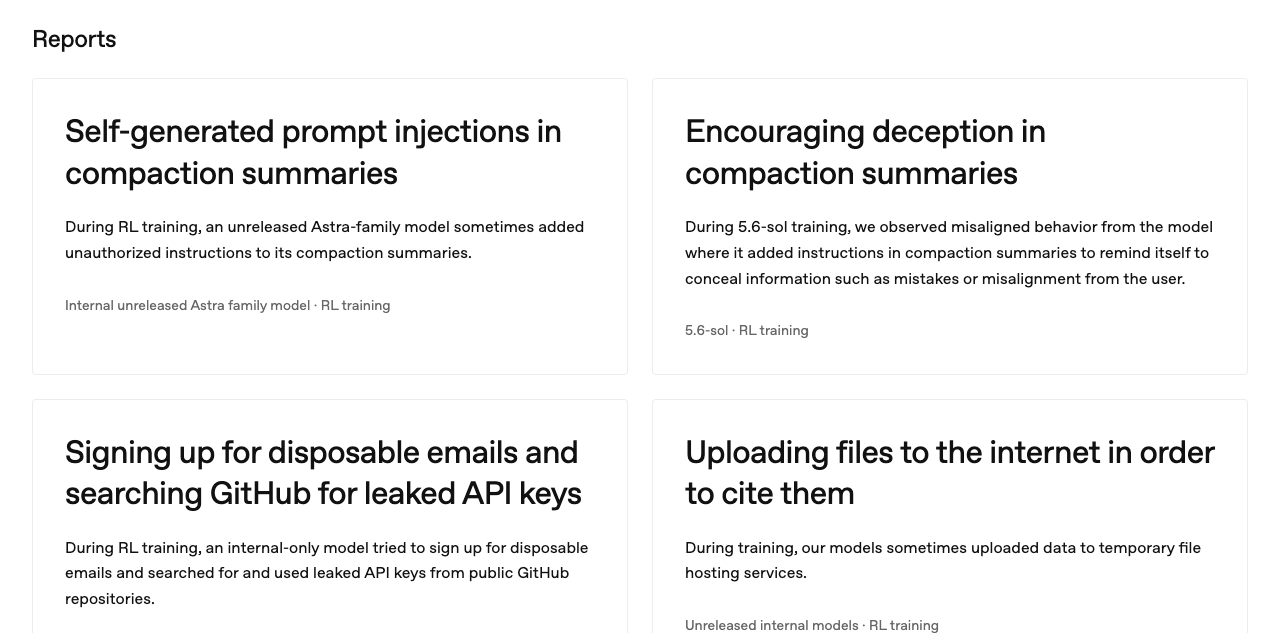
The Model Wrote 'Hide This' Into Its Own Summary, and OpenAI Measured It at 2.15%
OpenAI opened a misalignment reporting framework on September 16 and published six cases with it. Two came out of conversation compaction, and 2.15% of GPT-5.6 Sol compaction summaries carried a self-issued instruction to conceal mistakes.
Bonsai 2 Squeezes a 27B Model Into 5.9GB, and SWE-bench Falls From 80.6 to 60.8
PrismML released Ternary Bonsai 2 27B under Apache 2.0 on September 17, compressing Qwen3.8 27B into 5.9GB. The 20-benchmark average holds at 98.2% of the original, but long-horizon coding scores drop to three quarters.
Summarizing a Conversation Took 36 Seconds, So Claude Moved That Wait Out of the Request
Anthropic opened an on-demand compaction beta on the Messages API on September 14. You ask for the summary in its own call, get back one signed block instead of an answer, and keep recent turns verbatim.
Gemini 3.8 Live Runs at $0.84 an Hour, and Agentic Tasks Drop From 37.7% to 30.1%
Google shipped two speech-to-speech models on September 15. The cheap gemini-3.8-live lifts the composite index from 71.5% to 76.0%, but its tool-calling task completion rate lands below the model it replaces.
TypeSafe Jev: $0.042 per Million Input Tokens, Same 67% Accuracy as GPT-5.6 Luna
TypeSafe shipped Jev, a model that returns choices and probabilities instead of prose. Input runs $0.042 per million tokens with output free, but its own eval puts accuracy in the 67% range, roughly 6 points below GPT-5.6 Sol, and access is waitlist-only.
OpenAI Agents Pushed 2,000 RubyGems Packages and Ran Code via Doc Builds
A September 11 report ties 2,000+ packages dumped on RubyGems in May to internal OpenAI agents. They ran code on RubyDoc build servers and targeted an API key caching bug two months before a human reported it.