Blog
Notes and analysis on AI development.
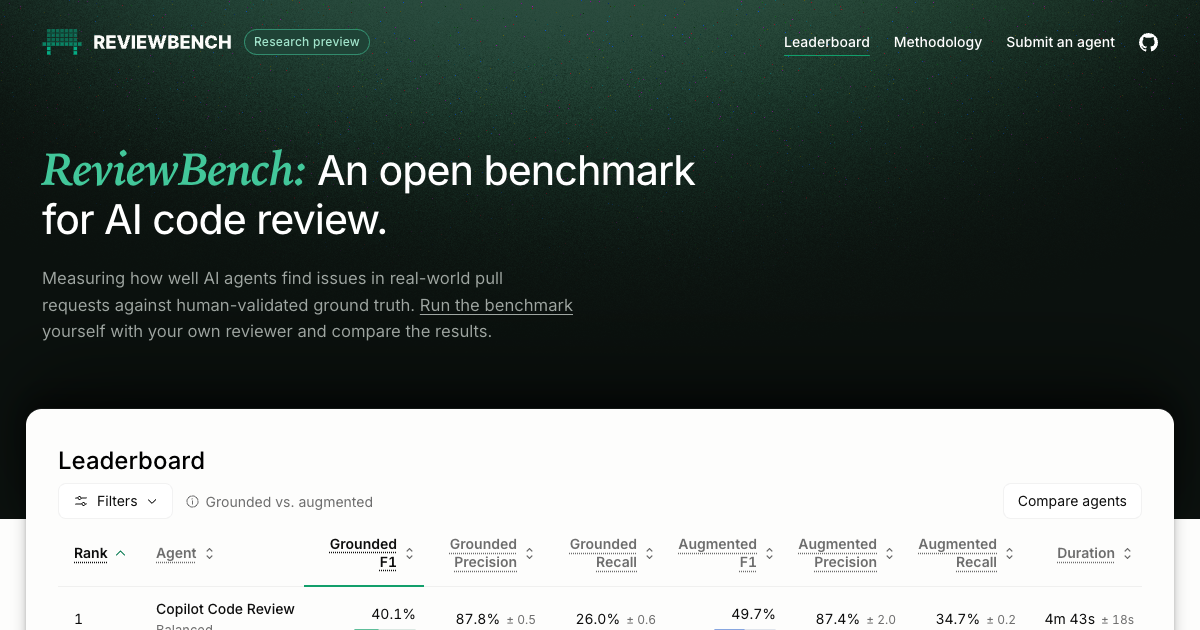
GitHub Opened a Benchmark for AI Code Review, and the Leader Finds 26% of Known Defects
GitHub published ReviewBench on October 5, scoring code review agents against 219 public PRs. Copilot Code Review leads at 87.8% precision but 26.0% recall, and on critical defects Codex scores 81 to Copilot 63.
Claude Haiku 5.5 Cuts Token Prices 90%, but Only Under 100,000 Tokens
Anthropic shipped Claude Haiku 5.5 on October 7. Input runs $0.10 per million tokens, a tenth of Haiku 4.5, but any prompt over 100,000 tokens pays $0.50, five times the headline rate.
Mistral Large 4 Ships at 1T Parameters, No Apache 2.0, Weights on October 27
Mistral opened Large 4 in API preview on October 6. Its Artificial Analysis intelligence index went from 9 on Large 3 to 38.4, input runs $1.36 per million tokens, and the weights land October 27 under a custom license.
Cloudflare Opens a Web Search API in Public Beta, $0.25 per 1,000 Searches Plus a 5% Credit Fee
Cloudflare opened a web search API inside AI Gateway as a public beta on October 2. Three providers, Ceramic.ai, Linkup, and Exa, are priced from $0.25 to $7.00 per 1,000 searches.
This Week in AI: GPT-6.1 Sol, Sonnet 5.5, and 13,000 Leaked Screenshots
OpenAI shipped GPT-6.1 Sol at DevDay on September 29 for the same $2 input price as its predecessor, and a day earlier Anthropic released Claude Sonnet 5.5 with 70.6% on Terminal-Bench.
Apple Is Tightening macOS Full Disk Access, and Your Terminal Hands It to Every Coding Agent
Apple announced on October 2, 2026 that it will add controls to macOS Full Disk Access, naming AI agents as the reason. The grant attaches to the terminal rather than the executable, so every coding agent launched there inherits it.
Claude Code Mods Run Inside the Process and Can Approve Tool Calls, With No Sandbox
Anthropic added Claude Mods to Claude Code v2.1.287 on October 1. Plugins now redraw the interface and intercept or pre-approve tool calls from inside the Claude Code process. There is no sandbox, mods can read environment variables and API keys, and the feature is on by default.
Gemini 4 Argon Leads 13 of 19 Benchmarks, and Only Cyber Defenders Can Call It
Google announced Gemini 4 Argon on September 30. Max output jumps from 64K to 1M tokens and 13 of the 19 rows in its own comparison table are outright wins, but there is no model ID, no launch date, and no public API at $2 per million input tokens.
Claude Now Stays Inside Seoul and Singapore, but Only up to Opus 5
AWS opened in-region Claude inference on Amazon Bedrock in Seoul and Singapore on September 29. Requests never leave the Region, but the newest 5.5 generation is not on the list: Seoul gets Opus 5 and Sonnet 5, Singapore gets Sonnet 5 alone.
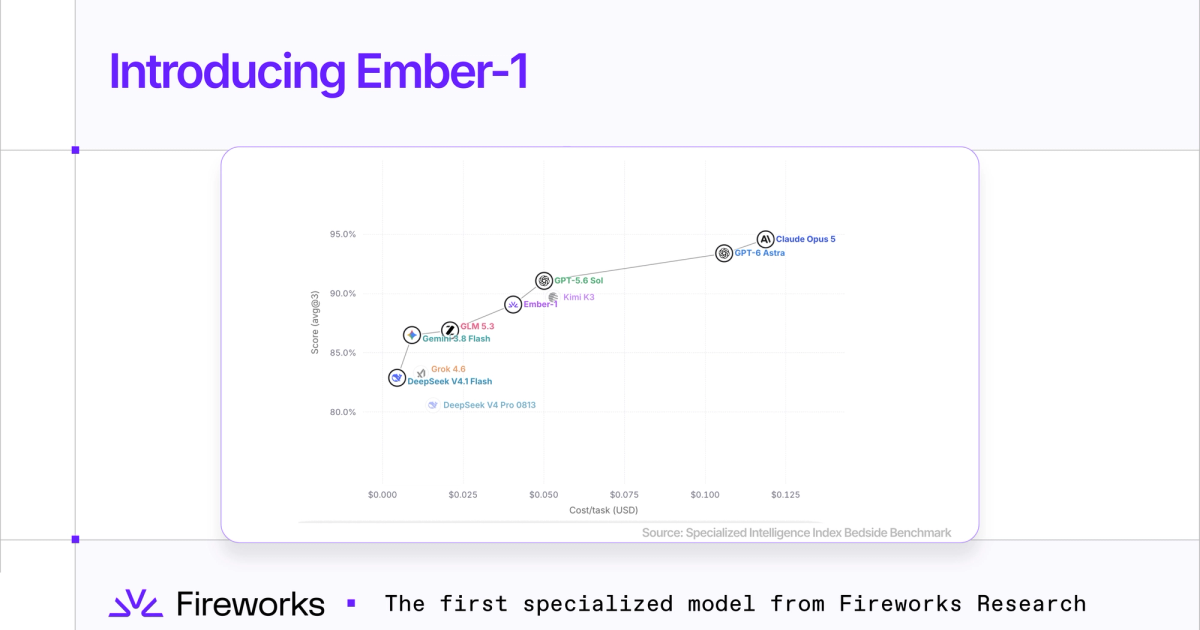
Fireworks Ember-1 Cuts Kimi K3 Tokens by 5.9% to 51.9% at the Same Price
Fireworks released Ember-1, a post-trained Kimi K3, on September 23 and shipped it to OpenRouter and Vercel AI Gateway on September 27. Per-token pricing matches K3 exactly at $3 in and $15 out, while token savings across five benchmarks range from 5.9% to 51.9%.
Claude Sonnet 5.5 Costs Half of Opus 5.5, and More per Task at max Effort
Anthropic released Claude Sonnet 5.5 on September 28. Pricing holds at Sonnet 5 levels, $2 per million input tokens, and Terminal-Bench 4.0 climbs from 10.3% to 70.6%, past Opus 5.5 at 66.4%.
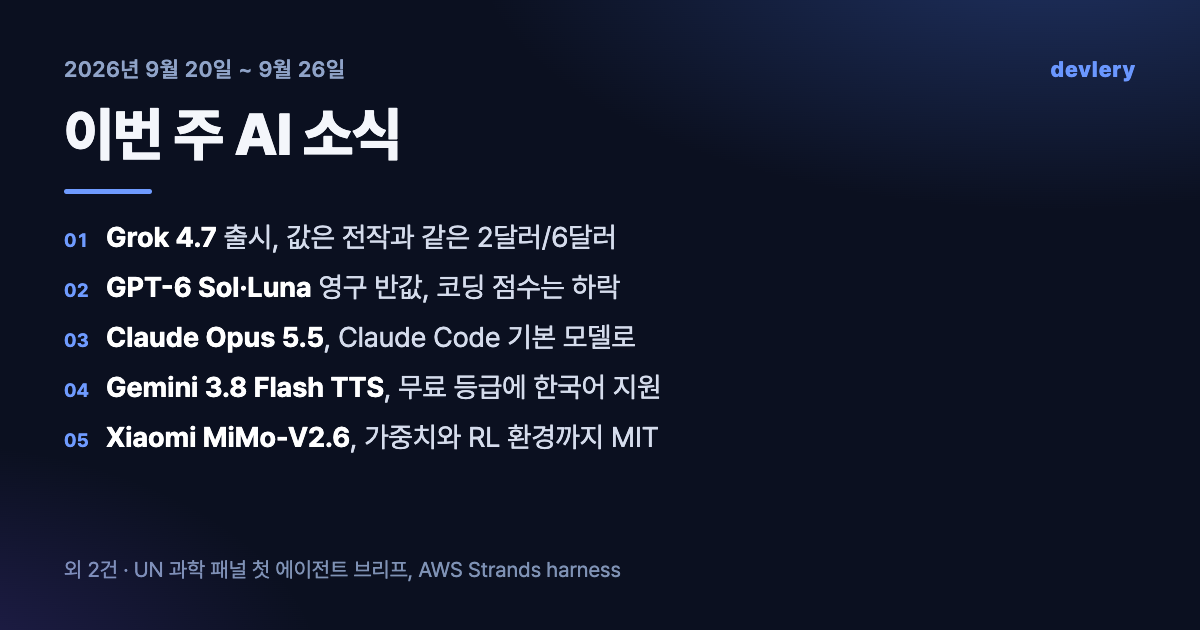
This Week in AI: Grok 4.7, Opus 5.5, and MiMo under MIT
xAI shipped Grok 4.7 on September 21 without raising the price, and the next day OpenAI cut GPT-6 Sol and Luna to half the previous rate while Anthropic released Claude Opus 5.5.